Diffusion-State Policy Optimization for Masked Diffusion Language Models
Abstract
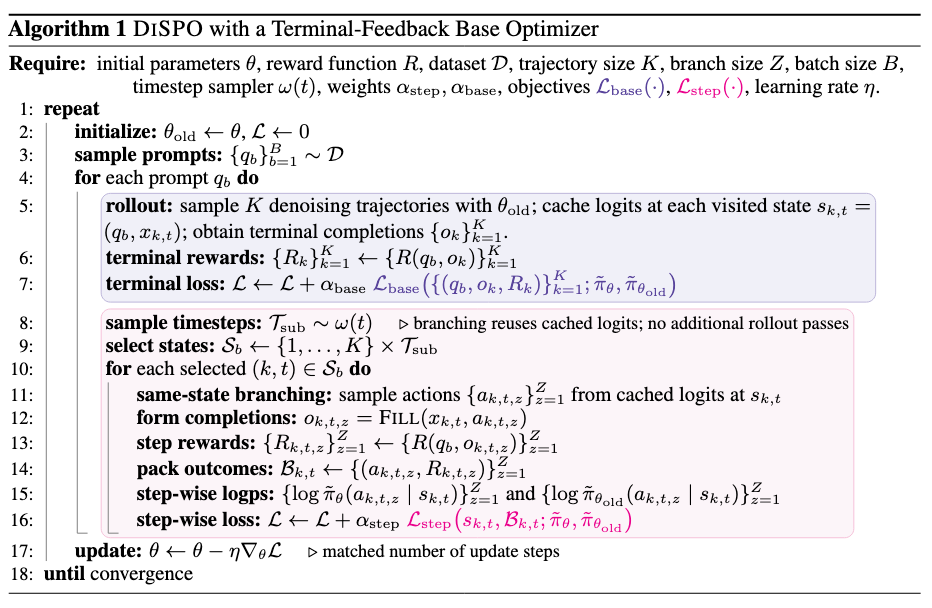
Masked diffusion language models generate text through iterative masked-token filling, but terminal-only rewards on final completions provide coarse credit assignment for the intermediate filling decisions that shape the generation process. We propose Diffusion-State Policy Optimization (DiSPO), a plug-in credit-assignment layer that directly optimizes intermediate filling decisions. At selected intermediate masked states, DiSPO branches by resampling the currently masked positions from rollout-cached logits, scores the resulting completions, and updates only the newly filled tokens, requiring no additional multi-step diffusion rollouts or optimizer steps. We formalize a fixed-state objective for branched completions and derive a policy-gradient estimator that reuses the same rollouts as terminal-feedback policy optimization. Experiments on LLaDA-8B-Instruct show that DiSPO consistently improves terminal-feedback baselines, including diffu-GRPO and SPG, on math and planning benchmarks under matched rollout compute and optimizer steps, supporting its use as a general plug-in for masked diffusion policy optimization.
DiSPO: Diffusion-State Policy Optimization
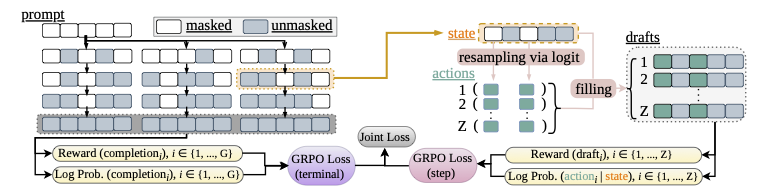
Conceptual overview. Left: Terminal-feedback PO assigns reward to the final denoising trajectory. Right: DiSPO branches from intermediate masked states using cached logits, scores the branched completions with the same reward, and updates only newly filled tokens.
Algorithm
Experiments
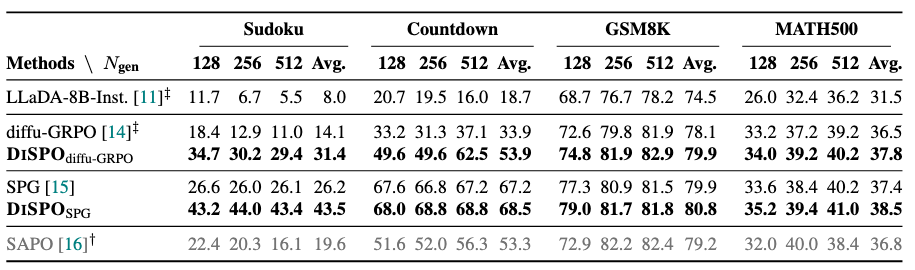
DiSPO on LLaDA. Exact-match accuracy (%) on planning and math reasoning, evaluated with Ngen in {128, 256, 512}. Matched-compute comparisons are made within each base optimizer: diffu-GRPO vs. DiSPOdiffu-GRPO and SPG vs. DiSPOSPG, with the same training Ngen = 256, multi-step diffusion rollout budget, and optimizer steps. † indicates a non-matched-compute reward-shaping baseline included for reference. ‡ indicates results reported by Zhao et al.
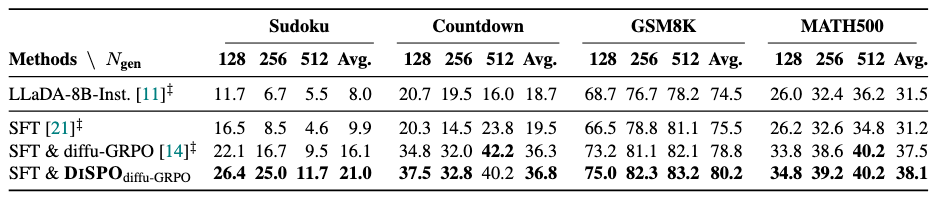
DiSPO on LLaDA-SFT. Under the same evaluation and matched-compute setup as the main results, DiSPO uses a conservative step weight (αstep = 0.1) and still improves SFT + diffu-GRPO across planning and math benchmarks. ‡ indicates results reported by Zhao et al.
BibTeX
@article{oba2026dispo,
  title = {Diffusion-State Policy Optimization for Masked Diffusion Language Models},
  author = {Oba, Daisuke and Furuta, Hiroki and Okazaki, Naoaki},
  journal = {arXiv preprint arXiv:2602.06462},
  year = {2026},
  url = {https://arxiv.org/abs/2602.06462}
}